Draw something!
I trained a neural network to recognize the 10 kinds of doodles shown below. Try to draw one of them and see if it can guess it correctly. Or, draw something random and confuse it.
- Cat
- Dog
- Wine Bottle
- Skateboard
- Snake
- Dumbbell
- Shark
- Guitar
- Car
- Palm Tree
Start drawing and the model's answer shows up here.
The model predicts:
How it works
When you draw, your strokes become a 28 × 28 grayscale image, the same format as the drawings the model learned from. A convolutional neural network (CNN) looks at that image, scores it against the 10 categories it knows, and the highest score becomes its prediction.
I didn't write rules for what a cat or guitar looks like. The network learned its own visual patterns from thousands of labeled example drawings.
-
Your drawing
28×28 input
-
Find simple patterns
32 filters
-
Combine patterns
64 filters
-
Weigh the patterns
64 neurons
-
Cat 98.1%
Prediction
10 outputs
How I trained it
I didn't get it right the first time. Each version followed the same loop: build a model, evaluate it, find the problem, change one thing, evaluate again.
The dataset
Every drawing comes from Google's Quick, Draw! dataset, where each doodle is stored as a 28 × 28 grayscale image with its correct label attached.
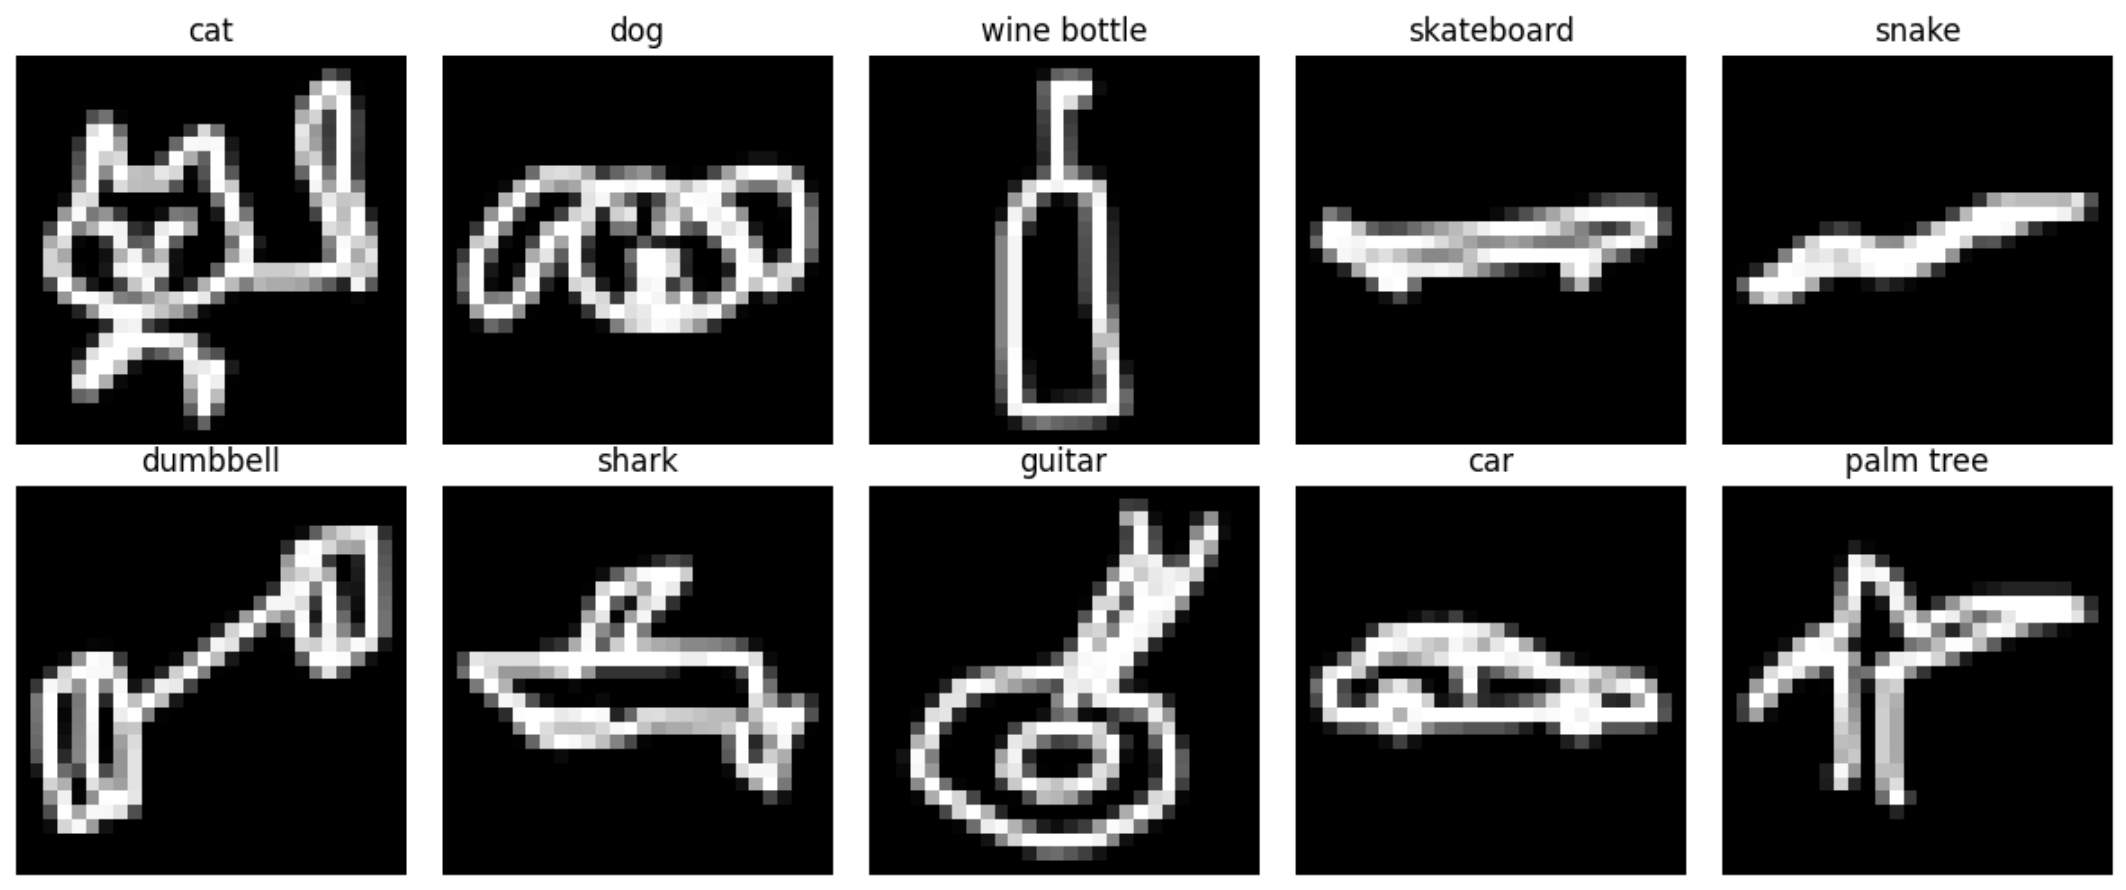
I took 10,000 drawings per category, 100,000 in all, and split them before training anything:
- 60K Training
- The examples the model learns from.
- 20K Validation
- Unseen drawings I used to compare models while developing.
- 20K Test
- Left untouched until the very end.
Model 1: Baseline
The first model was a plain dense network. Each image is stored as one long row of 784 numbers (its 28 × 28 pixels), which feed into a first hidden layer of 128 neurons, then a second hidden layer of 64 neurons, then an output layer of 10 values, one per category. Those 10 values are raw scores; a softmax function turns them into the probability that the drawing is each category. I trained it for 20 epochs (an epoch is one full pass through the training set).
Training accuracy kept improving, all the way to 96.03%, while validation accuracy peaked at 83.96% at epoch 7 and later fell to 82.23%. That's overfitting, also called high variance: the model became very good at drawings like the ones it trained on without doing as well on new drawings it hadn't seen.
Model 2: Regularization
L2 regularization adds a small penalty for large weights, meant to discourage the network from relying too heavily on any particular connection. With λ = 0.001 it didn't help: best validation accuracy went from 83.96% to 83.33%.
λ controls how strong the regularization penalty is. Later, after moving to the larger dataset, I tested 0, 0.0001, 0.001 and 0.01, and little or no regularization worked best among those settings.
Model 3: More Data
The same regularized network as Model 2, but trained on 200,000 drawings instead of 60,000, while the 20,000 validation and 20,000 test drawings stayed separate. With more examples to learn from, best validation accuracy rose to 86.92%.
Model 4: CNN
The dense models saw each image as one flat row of pixels, so they had no sense of which pixels sat next to each other. A convolutional neural network keeps the image's 2D layout. Its first layer slides small filters across the drawing to pick up edges and curves, pooling shrinks each result, and a second layer combines those into larger shapes before a small dense layer makes the call.
-
Drawing
28×28
-
Edges, curves
32 filters
-
Shrink
pooling
-
Shapes
64 filters
-
Shrink
pooling
-
Combine
64 neurons
-
Scores
10 outputs
Model progression
With the CNN chosen, I retrained it with early stopping, which stops training once validation loss stops improving and keeps the best epoch. Then I evaluated it once on the 20,000 test drawings set aside from the start. That's the model running on this page.
92.68%
Final test accuracy
- 92.79%
- best validation result, used during development
- 92.68%
- final test result, on held-out drawings
By category
Cats and dogs were the lowest-performing categories, and the model often confused them with each other.
How it runs here
This page doesn't retrain the model. I trained it beforehand in a Jupyter notebook with TensorFlow and Keras and converted it for the browser. The page loads that finished model and uses it to make predictions with TensorFlow.js, all in your browser. Your drawing isn't uploaded anywhere.
- Load trained modelmodel.json and a 488 KB weights file, fetched when this page opens
- You draweach stroke is recorded as a path of points
- Convert to 28×28your strokes are redrawn the way the Quick, Draw! images were made
- Prediction10 scores become percentages; the top one is shown with the next three